
Zigbee Mesh Capacity Limits Show Up Late
author
Zigbee mesh capacity issues rarely appear in early pilots, but they can surface late in deployment—when renewable energy sites, smart buildings, and distributed controls are already live. At NexusHome Intelligence, our IoT hardware benchmarking and protocol latency benchmark work turn hidden Zigbee mesh capacity and Matter standard compatibility risks into engineering truth for buyers, operators, and decision-makers.
For renewable energy operators, this is not a narrow networking problem. A delayed Zigbee mesh failure can affect battery room sensing, inverter status collection, HVAC coordination, occupancy-based lighting, and demand-response automation across assets that may run 24/7. In early proof-of-concept stages with 20 to 50 nodes, everything often looks stable. At 150, 300, or 500 nodes under real interference, hidden limits begin to emerge.
That late appearance is exactly what makes Zigbee mesh capacity risk so expensive. By the time packet loss, route instability, and battery drain become visible, the site may already be commissioned, integrated into an energy management platform, and tied to service-level expectations. For researchers, operators, procurement teams, and enterprise decision-makers, the question is no longer whether Zigbee can work, but under what load, topology, and environmental conditions it remains trustworthy.
Why Zigbee Mesh Capacity Problems Surface Late in Renewable Energy Deployments
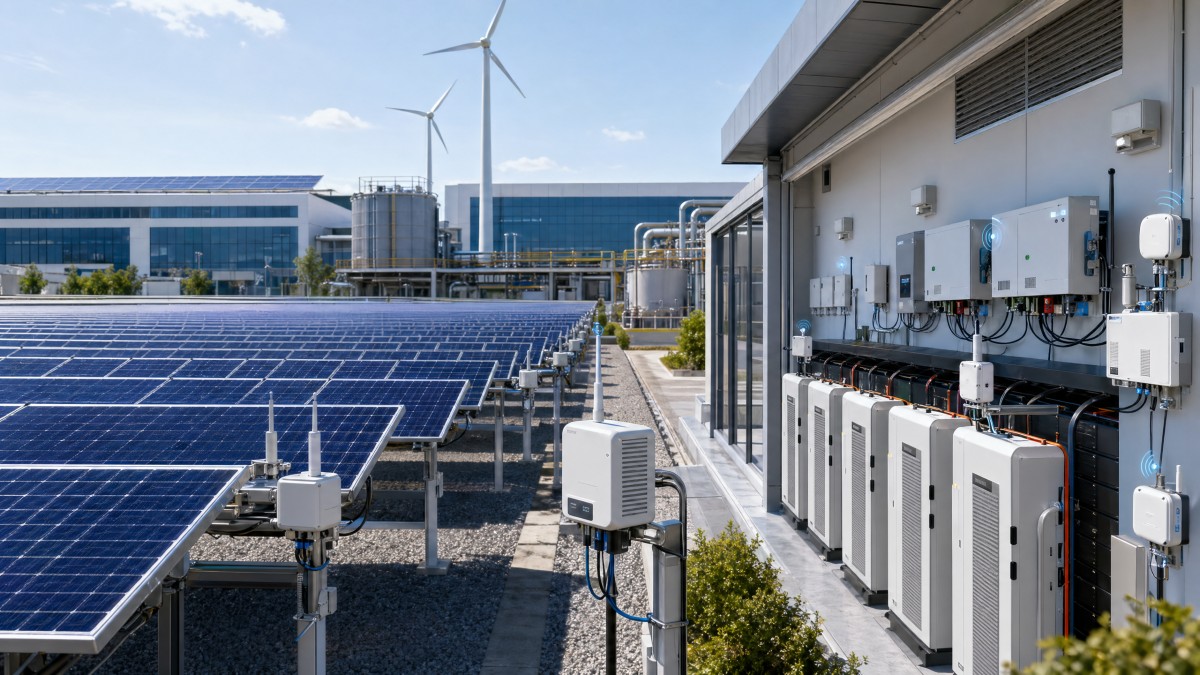
Renewable energy environments create a deceptive testing gap. A pilot in a clean lab or model floor may use 1 coordinator, 10 to 20 routers, and fewer than 50 end devices. A live solar-plus-storage facility, microgrid building, or energy-efficient commercial campus can quickly scale to 200 to 800 endpoints when submeters, temperature sensors, relay modules, lighting controls, access nodes, and equipment health monitors are included.
The second reason is traffic behavior. Capacity is not only about how many devices join the Zigbee network. It is also about how often they transmit, how many hops they need, and whether bursts occur at the same time. In renewable energy control systems, 5-minute telemetry intervals may coexist with 1-second alarm bursts, OTA maintenance windows, and rule-based automation triggers. A network that appears healthy at average load can still fail at peak concurrency.
Interference further delays symptom visibility. Battery inverters, switchgear rooms, steel enclosures, concrete structures, elevator motors, and dense Wi-Fi occupancy all change radio behavior over time. What passes site acceptance in Week 1 may degrade in Month 3 after full tenant occupancy, seasonal HVAC shifts, or added subpanels. This is why NHI treats protocol performance as a long-duration benchmark, not a one-day checkbox.
A final factor is route fragility. Zigbee mesh often looks resilient because it self-heals, but self-healing is not free. Re-routing can increase latency from tens of milliseconds to several hundred milliseconds, especially when hop count rises from 2 to 5. In distributed energy applications, that may not break a dashboard, but it can reduce the reliability of synchronized control sequences and increase battery consumption in sleepy end devices.
Common triggers that reveal late-stage mesh limits
- Node count expansion after handover, especially when a site grows from 80 devices to more than 250.
- Control policy changes that increase reporting frequency from every 10 minutes to every 30 to 60 seconds.
- Building occupancy and equipment commissioning that introduce new 2.4 GHz interference sources.
- Firmware updates that add richer telemetry payloads, increasing airtime and retransmission pressure.
Early pilot versus live renewable energy network behavior
The comparison below shows why pilot success should never be used as the sole procurement signal for Zigbee-based renewable energy controls.
The key takeaway is simple: capacity failure is usually cumulative. It comes from the interaction of node density, airtime contention, routing complexity, and environmental interference rather than from a single obvious defect.
What Capacity Limits Mean for Solar, Storage, and Smart Building Energy Systems
In renewable energy operations, the business cost of Zigbee mesh capacity problems is often indirect at first. A dashboard may still load, and most devices may still appear online. But subtle degradation matters. A 2% to 5% increase in missed reports from battery room sensors can reduce confidence in thermal trend detection. A repeated 300 ms to 500 ms delay in relay execution can weaken load-shedding sequences during demand peaks.
For operators, one of the most visible effects is maintenance noise. As the mesh nears its practical capacity, alarms become less trustworthy. Teams may chase intermittent offline notifications, replace healthy batteries too early, or schedule unnecessary truck rolls. In a portfolio of 10 to 30 distributed sites, even a small rise in false maintenance events can materially increase OPEX over 12 months.
For procurement teams, the problem often shows up after contract award. Suppliers may state support for Zigbee 3.0 or Matter bridging, but those claims rarely describe tested node ceilings, average latency per hop, or behavior under 30% to 60% channel occupancy. Without this detail, buyers may compare products on unit cost while ignoring network-scale performance that determines total lifecycle value.
For enterprise decision-makers, capacity instability has strategic consequences. A renewable energy site expected to support future electrification, occupancy analytics, and distributed flexibility services needs protocol headroom. A network designed for today’s 120 endpoints may struggle when expansion pushes it to 250 or 400. This is why network planning must be treated as infrastructure planning, not accessory procurement.
Operational impact by renewable energy use case
Different applications tolerate different levels of latency, packet loss, and battery drain. The table below helps align Zigbee mesh design with energy-sector risk tolerance.
The most important point is that “good enough” depends on function. A mesh suitable for periodic monitoring may be inadequate for control-heavy energy automation. Buyers should evaluate application classes separately instead of assuming a single capacity figure applies to every workload.
Three hidden cost centers
- Battery replacement acceleration when end devices retry transmissions or remain awake longer than planned.
- Commissioning rework, including extra routers, channel redesign, and gateway repositioning after occupancy.
- Software-side workaround costs, where analytics teams filter noisy data instead of receiving clean network telemetry.
How to Evaluate Zigbee Mesh Capacity Before Procurement and Deployment
A reliable evaluation method starts with practical limits, not theoretical maximums. Many teams ask how many devices Zigbee supports, but a better question is how many devices the chosen architecture supports at the target reporting interval, in the target RF environment, with the intended battery life. For renewable energy projects, that means testing a topology that reflects actual panel rooms, utility spaces, rooftops, plant rooms, and tenant zones.
At NHI, protocol benchmarking focuses on measurable thresholds. Examples include median latency at 1, 3, and 5 hops; message success rate during 15-minute traffic bursts; battery impact after repeated route changes; and gateway recovery time after coordinator restart. These tests are especially useful when suppliers claim compatibility across Zigbee, Thread, BLE, and Matter without publishing stress-case behavior.
Procurement teams should request test conditions in writing. A vendor statement such as “supports 200 devices” is incomplete unless it includes router count, payload size, average reporting interval, retransmission profile, and interference conditions. A 200-node network with 10-minute telemetry is not the same as a 200-node network with 30-second updates and event-driven relay commands.
Decision-makers should also plan for growth. In energy retrofits and phased developments, a 25% to 40% capacity reserve is often more prudent than designing to today’s exact node count. That reserve helps absorb later demands such as indoor air quality monitoring, EV charging zone sensing, smart access, or asset health extensions.
A practical 5-step assessment framework
- Define device classes: separate sleepy sensors, always-powered routers, relays, and high-frequency telemetry nodes.
- Map reporting behavior: identify periodic intervals such as 30 seconds, 5 minutes, and 15 minutes, plus alarm bursts.
- Model physical topology: count walls, steel barriers, switch rooms, rooftop zones, and vertical shafts.
- Stress-test scale: simulate at least 1.2x to 1.5x the planned launch node count to expose late-stage limits early.
- Validate integration: confirm Matter bridge behavior, gateway buffering, and API responsiveness during congestion.
Evaluation metrics that matter in renewable energy projects
The following criteria give procurement and engineering teams a stronger basis than simple device-count claims.
These metrics help convert vague compatibility language into procurement-grade evidence. They also make cross-vendor comparison more realistic, especially when evaluating hidden champions in the OEM or ODM supply chain.
Common buying mistake
A frequent error is selecting devices with strong component-level specifications but weak network-scale validation. High-quality PCBA, low standby power, or impressive sensor accuracy do matter, but they do not guarantee reliable mesh behavior under interference and expansion. Network proof must be treated as its own acceptance category.
Matter Compatibility, Multi-Protocol Growth, and Long-Term Network Design
Renewable energy infrastructure is increasingly multi-protocol. A single site may contain Zigbee sensors, Thread-based room controls, BLE commissioning tools, Modbus-connected meters, and cloud APIs feeding a building or microgrid management system. In this environment, Matter compatibility is relevant, but it should never be mistaken for a guarantee of identical performance across protocols or bridges.
The late-stage problem often appears when Zigbee traffic must pass through a bridge into a Matter-aware control stack. If the underlying Zigbee mesh is already close to its practical limit, the bridge only exposes the issue more clearly. Operators may blame Matter standard compatibility, but the root cause can still be route instability, coordinator overload, or excessive retransmissions on the Zigbee side.
For long-life renewable energy assets, protocol strategy should cover at least 3 to 5 years of expansion. That means defining which functions remain local and deterministic, which can tolerate cloud delay, and which workloads may migrate toward Thread or other architectures over time. The aim is not protocol purity; it is operational resilience and measurable performance.
NHI’s position is straightforward: interoperability claims should be benchmarked under real mixed-protocol conditions. A vendor may truthfully state that a product “works with Matter,” yet still fail to provide acceptable performance when 120 Zigbee endpoints, 20 automation rules, and concurrent status polling are active. Procurement teams should therefore test bridge behavior under load, not just onboarding success.
Design principles for future-ready deployments
- Keep critical energy controls on the most predictable local path, with minimum unnecessary bridging.
- Segment dense device clusters rather than forcing all sensors through one oversized Zigbee domain.
- Reserve protocol translation for supervisory coordination, dashboards, and non-time-critical orchestration.
- Document firmware, channel plan, router placement, and commissioning procedures so expansions remain controlled.
FAQ for buyers and operators
How many Zigbee devices are safe for a renewable energy site?
There is no universal safe number. Practical limits depend on router density, message frequency, payload size, interference, and hop count. In many real sites, performance risks begin well before theoretical maxima. A design target with 20% to 40% spare capacity is usually more robust than aiming for the absolute advertised ceiling.
Is Zigbee still a good choice for energy monitoring and smart control?
Yes, if the workload is matched to the topology and tested under realistic conditions. Zigbee can be highly effective for distributed sensing, lighting, and many relay functions. Problems arise when buyers assume lab-scale performance will automatically hold at live-site scale without benchmark verification.
What should procurement ask suppliers before awarding a project?
Ask for node-count test conditions, hop-based latency data, burst-load success rates, battery life assumptions, gateway recovery behavior, and Matter bridge performance under congestion. Also request whether results were measured in a controlled chamber, office floor, or interference-rich industrial environment.
How long does proper validation usually take?
For a serious renewable energy deployment, allow 2 to 4 weeks for topology modeling, staged stress testing, and mixed-traffic validation. Faster checks can confirm basic function, but they rarely expose the late-stage capacity limits that matter most.
Turning Protocol Claims Into Procurement-Grade Engineering Truth
The renewable energy sector is moving toward denser sensing, more distributed control, and tighter integration between building intelligence and energy infrastructure. In that context, Zigbee mesh capacity limits are not edge cases. They are predictable risks that simply emerge later than most pilots are designed to reveal. The cost of discovering them after commissioning is far higher than the cost of benchmarking them early.
NexusHome Intelligence exists to close that gap between marketing language and operational evidence. By benchmarking Zigbee 3.0 mesh behavior, protocol latency, hardware integrity, and Matter-related interoperability under stress, NHI helps global buyers and project teams identify which products and manufacturing partners can actually support smart energy outcomes at scale.
If you are planning a solar-plus-storage rollout, an energy-efficient commercial retrofit, or a multi-site smart building program, treat network capacity as a core engineering decision. Validate node density, traffic profile, router placement, and bridge performance before rollout, not after complaints begin. This is especially important for procurement teams comparing vendors whose datasheets appear similar but whose network behavior may differ dramatically in the field.
To reduce late-stage failure risk and improve supplier selection, contact NHI for benchmarking support, product evaluation guidance, or a custom protocol assessment aligned with your renewable energy deployment. Get a data-driven plan, review the real bottlenecks, and move forward with greater confidence.
Protocol_Architect
Dr. Thorne is a leading architect in IoT mesh protocols with 15+ years at NexusHome Intelligence. His research specializes in high-availability systems and sub-GHz propagation modeling.
Related Recommendations
- Dr. Aris ThorneIEEE 802.15.4z-2026 Sets New UWB Compliance Signal
- Dr. Aris ThorneIEEE 802.15.4z-2026 Sets New Zigbee UWB Test Bar
- Dr. Aris ThorneIEEE 802.15.4z-2026 Sets New UWB Benchmark for Zigbee Tech
- Dr. Aris ThorneIEEE 802.15.4-2026 Lifts Zigbee Mesh to 256 Nodes
- Dr. Aris ThorneZigbee Mesh Capacity in the USA: How Many Devices Can a Network Handle Reliably?
- Dr. Aris ThorneEU Enforces Matter 1.3 for Zigbee Device Imports
- Dr. Aris ThorneTelink Joins CSA Board as Multi-Protocol SoC Output Scales
- Dr. Aris ThorneEU Enforces EN 303 647 v2.1.1 for Zigbee Exports
- Dr. Aris ThorneEN 303 647 v2.1.1 Now Mandatory for Zigbee Devices
- Dr. Aris ThorneGSHE 2026 Adds Matter/Zigbee Sourcing Zone
Analyst